
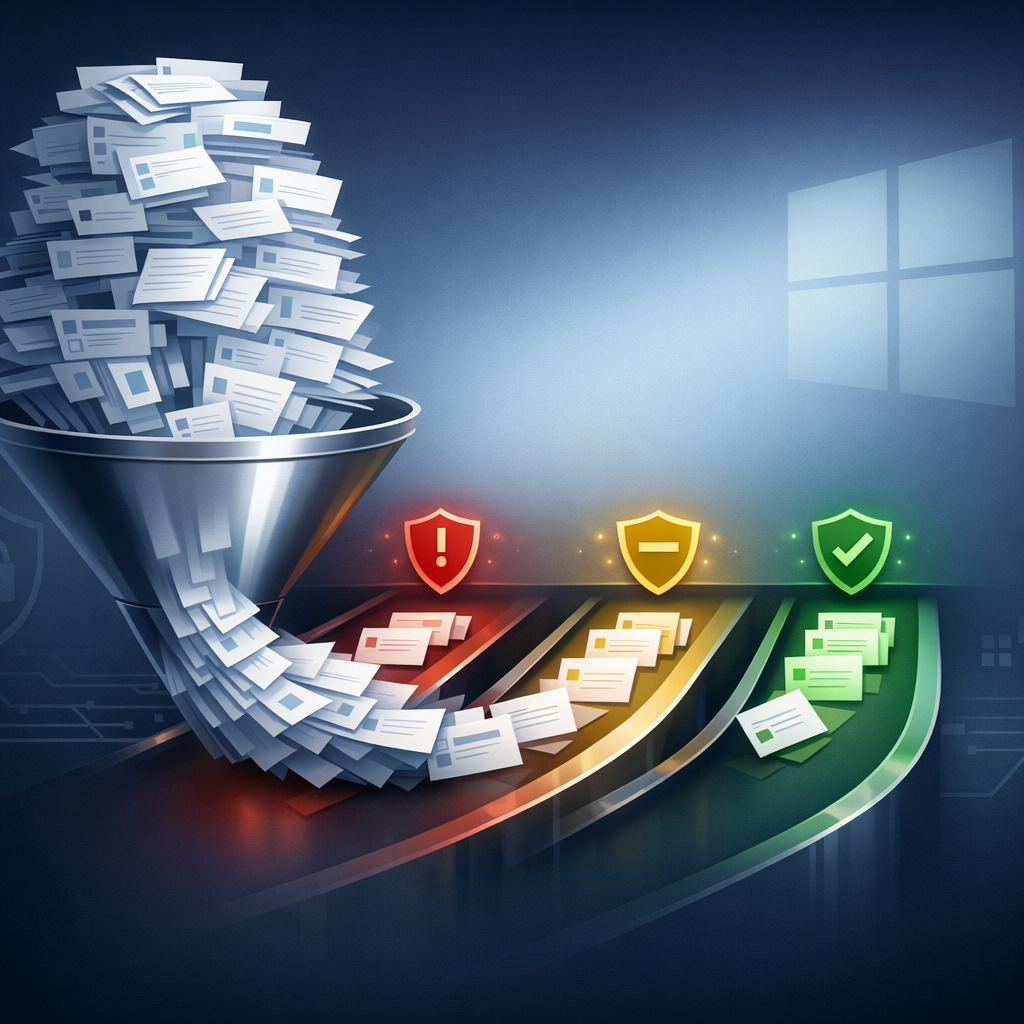
Tomorrow is the second Tuesday of October. If September is any guide, you are about to receive another very large pile of CVEs. September’s release was Microsoft’s biggest ever: 966 flaws, up from about 570 in July and 400 in August. The article ties the jump to Microsoft’s AI-assisted vulnerability discovery. If that is right, this is not a spike. It is the new baseline.
Why raw counts stop being useful
Roughly 438 of September’s fixes were elevation-of-privilege bugs, with about 258 remote code execution and 173 information disclosure. Around 105 were rated Critical. (The published figures do not fully reconcile, so treat them as approximate.) Malwarebytes counted 964 that customers actually needed to act on, after removing cloud-side fixes Microsoft applied itself.
No team reads 964 CVE descriptions. The useful question is not “what did Microsoft fix?” but “which of these changes my risk on my estate this month?” Here is a framework that answers it in an hour.
Step 1: Sort by exploitation, not severity
CVSS tells you how bad a bug could be. It does not tell you whether anyone is using it. Start with three signals:
- Microsoft’s “Exploitation Detected” flag. September had two, both local privilege escalations to SYSTEM.
- CISA’s Known Exploited Vulnerabilities catalog. Anything added gets a deadline you can point to when asking for emergency change approval.
- Public proof-of-concept code. A working exploit changes the timeline even without confirmed attacks.
Anything in these buckets goes into an accelerated ring, within days rather than weeks.
Step 2: Filter by what you actually run
A large share of each month’s CVEs touch components that may not exist on your devices. September included flaws in DNS Server, Remote Desktop Services, Exchange, SharePoint and SQL Server, plus cloud-service entries. If you do not run a role, the CVE is informational. Map the release against your server roles and installed products so the real list shrinks quickly.
Step 3: Weight by exposure and blast radius
Among the remainder, rank by where the vulnerable component sits:
- Internet-facing or network-reachable services (RDS gateways, DNS, mail). Remote code execution on these is the top tier.
- Identity infrastructure — domain controllers, AD FS, Entra-connected services. Compromise here is domain-wide.
- Management plane — your Intune, SCCM or RMM servers. They can push code to everything.
- Standard endpoints. Largest count, lowest per-device value, but the bulk of EoP bugs land here.
Step 4: Treat the EoP flood as a privilege problem
With EoP making up close to half of the release, you cannot patch your way to safety one CVE at a time — there will always be an unpatched window. What you can do is shrink what an attacker gains from each one. Standing local admin, shared admin credentials and over-privileged service accounts all turn a “moderate” local bug into an immediate compromise. Every admin right you remove makes next month’s EoP count less important.
Step 5: Make rings fast and boring
A triage framework is only as good as your deployment mechanics. Aim for:
- A small pilot ring that receives updates within 24–48 hours of release.
- A broad ring at day 5–7.
- An emergency ring definition (who, how, who approves) agreed in advance, so exploited-in-the-wild fixes do not wait on a change board.
- Automatic restarts with deadlines. Staged-but-not-restarted is the most common silent gap.
What to do now
- Before tomorrow, write down your emergency-ring criteria in one paragraph: “exploited, KEV-listed, or public PoC means days, not weeks.”
- Pre-build a list of the server roles and products you run, so scoping the release takes minutes.
- Check that pilot-ring devices are healthy and representative; a pilot nobody reads feedback from is not a pilot.
- Pull current pending-reboot counts and set a restart deadline policy.
- Measure your local admin population and pick a reduction target for the quarter.
- After release day, record time-to-patch per ring. If emergency fixes took longer than you said they would, fix the process, not the people.
Volume will keep rising. The teams that cope are not patching faster across the board — they are deciding sooner which fixes deserve to be fast.